
DoHun Lee
About Me
I am a Ph.D. student at the Kim Jaechul Graduate School of AI, KAIST, advised by Prof. Jong Chul Ye. I received my M.S. in Artificial Intelligence from KAIST in Feb. 2026, and my B.S. in Computer Science from KAIST in Feb. 2024.
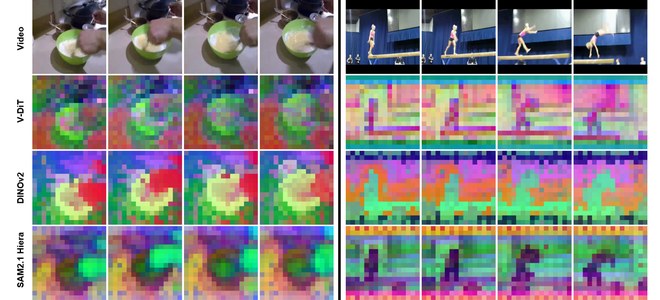
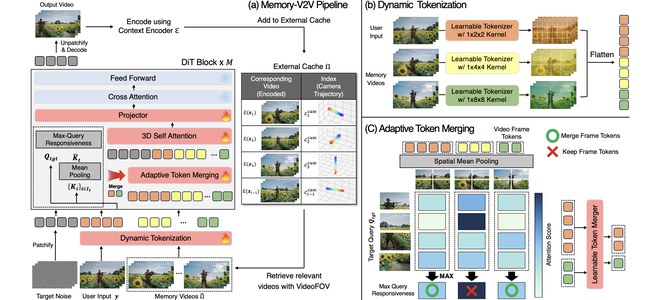
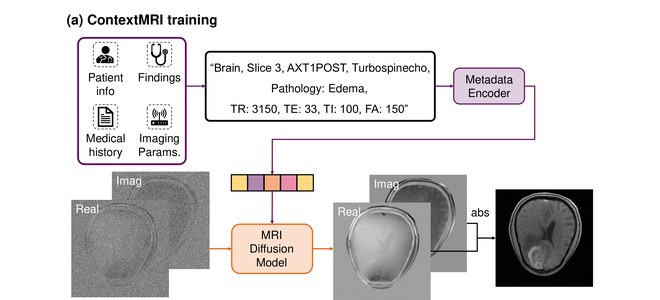
My research so far has focused on generative models, especially video diffusion models: improving temporal consistency without additional training, training video diffusion transformers with self-supervised vision encoders, and equipping video-to-video diffusion models with memory for consistent multi-turn editing (during my internship at Adobe Research). I have also worked on diffusion models for inverse problems, such as compressed sensing MRI.
These days, I am particularly interested in long-term world modeling, out-of-sight dynamics, and robotics.
Research Interests
- Current: Long-term world modeling, out-of-sight dynamics, robotics
- Previous: Video generation & editing with diffusion models, diffusion models for inverse problems
News
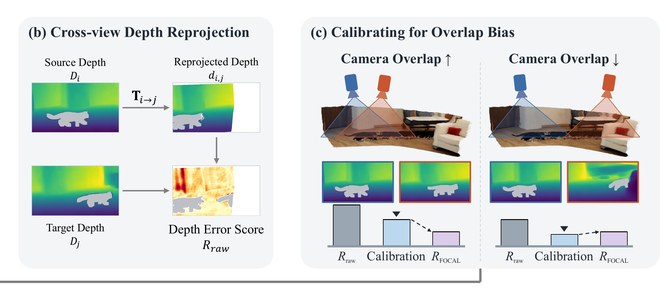
- [Oct. 2026] New preprint GeoFix is released on arXiv.
- [Sep. 2026] Started my Ph.D. at KAIST AI.
- [Jun. 2026] Memory-V2V is accepted to ECCV 2026!
- [Feb. 2026] Received my M.S. degree from KAIST AI.
- [Feb. 2025] VideoGuide and MotionPrompt are accepted to CVPR 2025!
Publications
* denotes equal contribution
-
 arXiv
Improving Video Diffusion Transformer Training by Multi-Feature Fusion and Alignment from Self-Supervised Vision EncodersarXiv preprint, 2025
 arXiv
 ECCV
 MedIA
 CVPR
 CVPR
 arXiv
Education
-
Ph.D. in Artificial Intelligence, KAIST (Sep. 2026 – Present)
Advisor: Prof. Jong Chul Ye -
M.S. in Artificial Intelligence, KAIST (Mar. 2024 – Feb. 2026)
Advisor: Prof. Jong Chul Ye -
B.S. in Computer Science, KAIST (Mar. 2018 – Feb. 2024)
Minor in Electrical Engineering
Honors & Scholarships
- National Science & Technology Scholarship (since 2022)
- Dean's List, School of Computing, KAIST (2019, 2020)
- Most Creative Research, Environmental Science and Future Energy, ISSF (2017)
Powered by Jekyll and Minimal Light theme.